100% Offline Sovereign HR Artificial Intelligence with Ollama
What is 100% offline HR artificial intelligence with Ollama?
Closed-circuit processing on your local machine
Direct localhost:11434 connectivity with automated discovery
Absolute compliance with Algerian data protection statutes
Unlimited generations without token consumption fees
Confidential data leaks, internet downtime, and regulatory transfer hurdles
The INARA method: Multi-provider inference hub with local priority
Local Ollama setup
Install the open-source Ollama engine on your PC or local intranet server with the open-weight models of your choice (Llama 3, Mistral, Gemma).
Automated 1-click discovery
In the INARA AI Center, click "Discover" to instantly register all LLM models installed on your local machine.
Exclusive Local Mode
Activate local lock-down: the application disables all external network calls and operates in total autonomy.
Unlimited generation & analysis
Draft job profiles, design candidate tests, and audit resumes without counting tokens or incurring per-request charges.
Key Capabilities
Automated Ollama Model Detection
Instant recognition of models installed on http://localhost:11434 with Bearer token authentication support for secured corporate intranets.
Exclusive Local Mode Toggle
Security lock-down preventing any outbound connections to third-party endpoints, tailored for classified corporate environments.
Network Status & Error Diagnostics
Integrated console explaining HTTP status codes (400, 401, 403, 429, 500, 503) with clear troubleshooting guidance.
Multi-Key Management & Hot-Swapping
Switch between local Ollama models and cloud providers (Gemini, Groq, OpenRouter) based on the sensitivity of each operational task.
Technical Comparison: Cloud Models vs Local Ollama Deployment
Comparative analysis of performance, confidentiality, and operational costs across architectures.
| Architecture Criterion | Remote Cloud AI Models | Local Ollama Instance |
|---|---|---|
| Network Data Flow | Encrypted queries sent over public internet | Zero outbound network packets (100% confined) |
| Operational Cost | Billed per token in foreign currency | Completely free and unlimited after license purchase |
| Network Availability | Inoperable during internet outages | Continuous operation even in disconnected remote zones |
| Supported Models | Gemini Flash, Groq LPU, OpenRouter models | Llama 3, Mistral, Gemma, and local open-weight models |
| Law 18-07 Compliance | Demands strict pre-flight anonymization | Native compliance through absolute local confinement |
Initial Challenge
Modernize talent recruitment and HR competency engineering while complying with an absolute regulatory ban on third-party cloud hosting.
The INARA Solution
Deployed INARA RH paired with a local Ollama instance (Mistral 7B) on talent acquisition workstations.
Measured Outcomes
INARA HR modules deployed in this solution
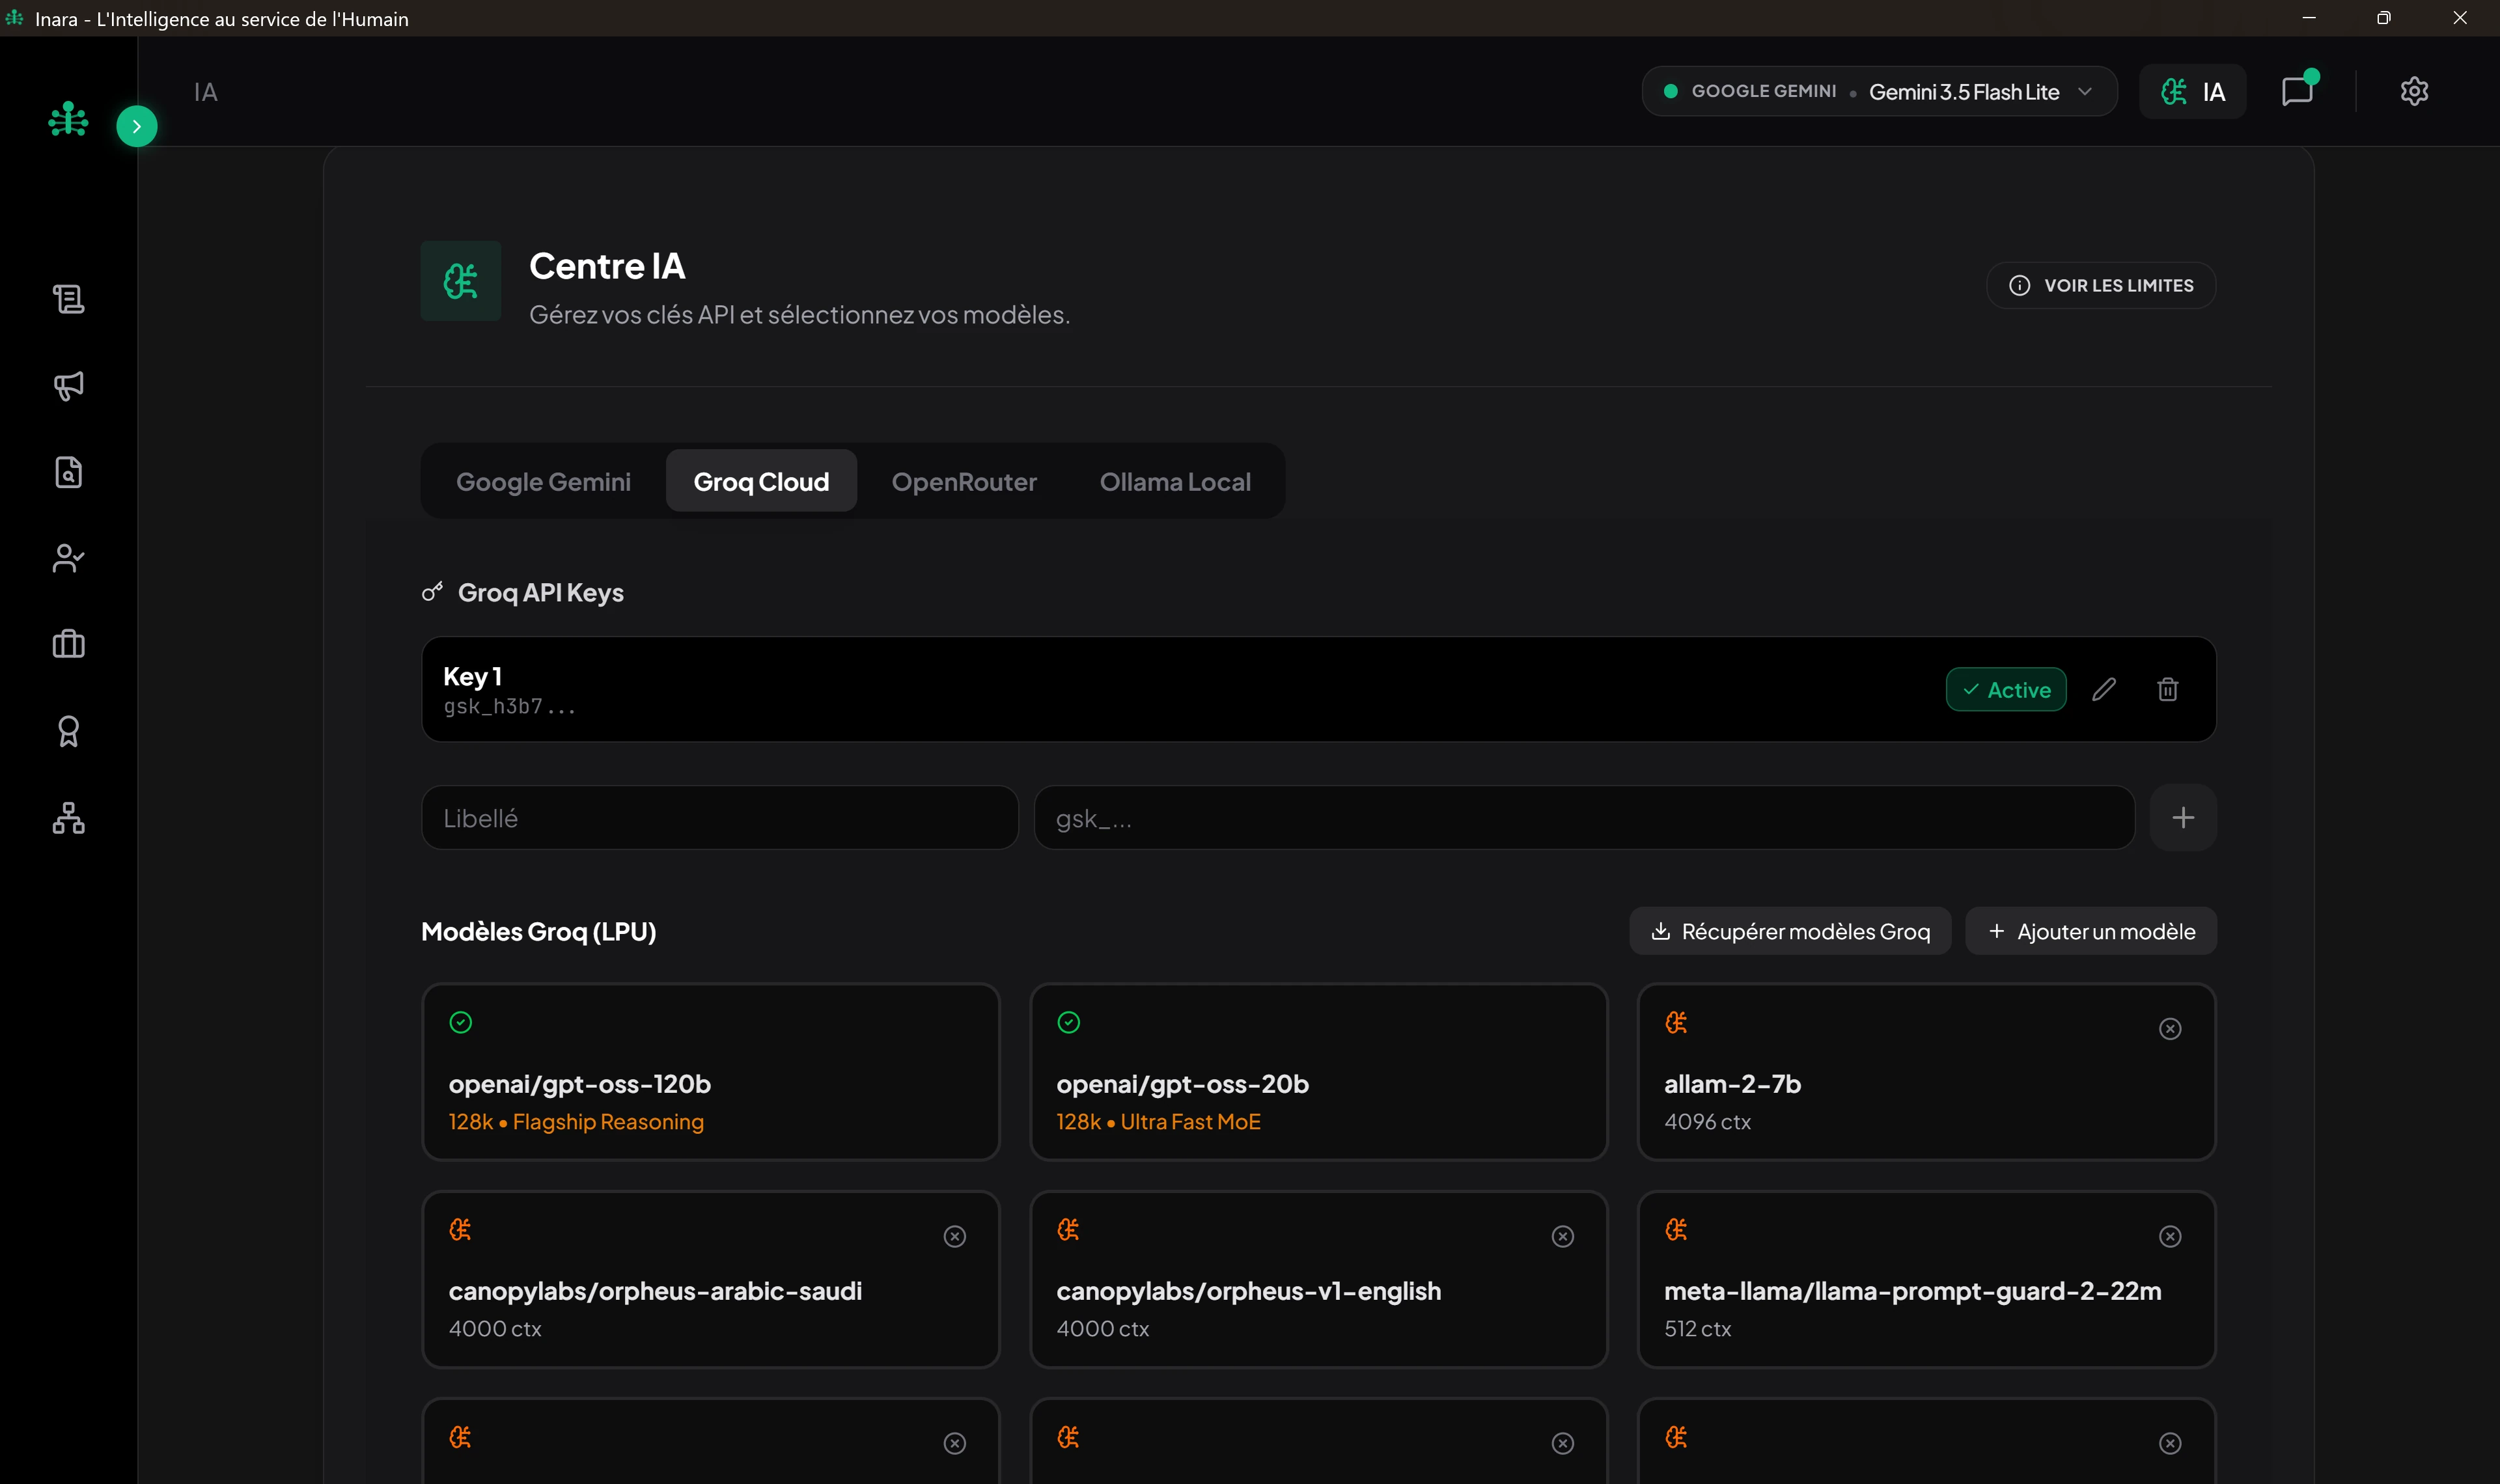
AI Center & Models
Supervises Ollama connectivity and manages local inference models
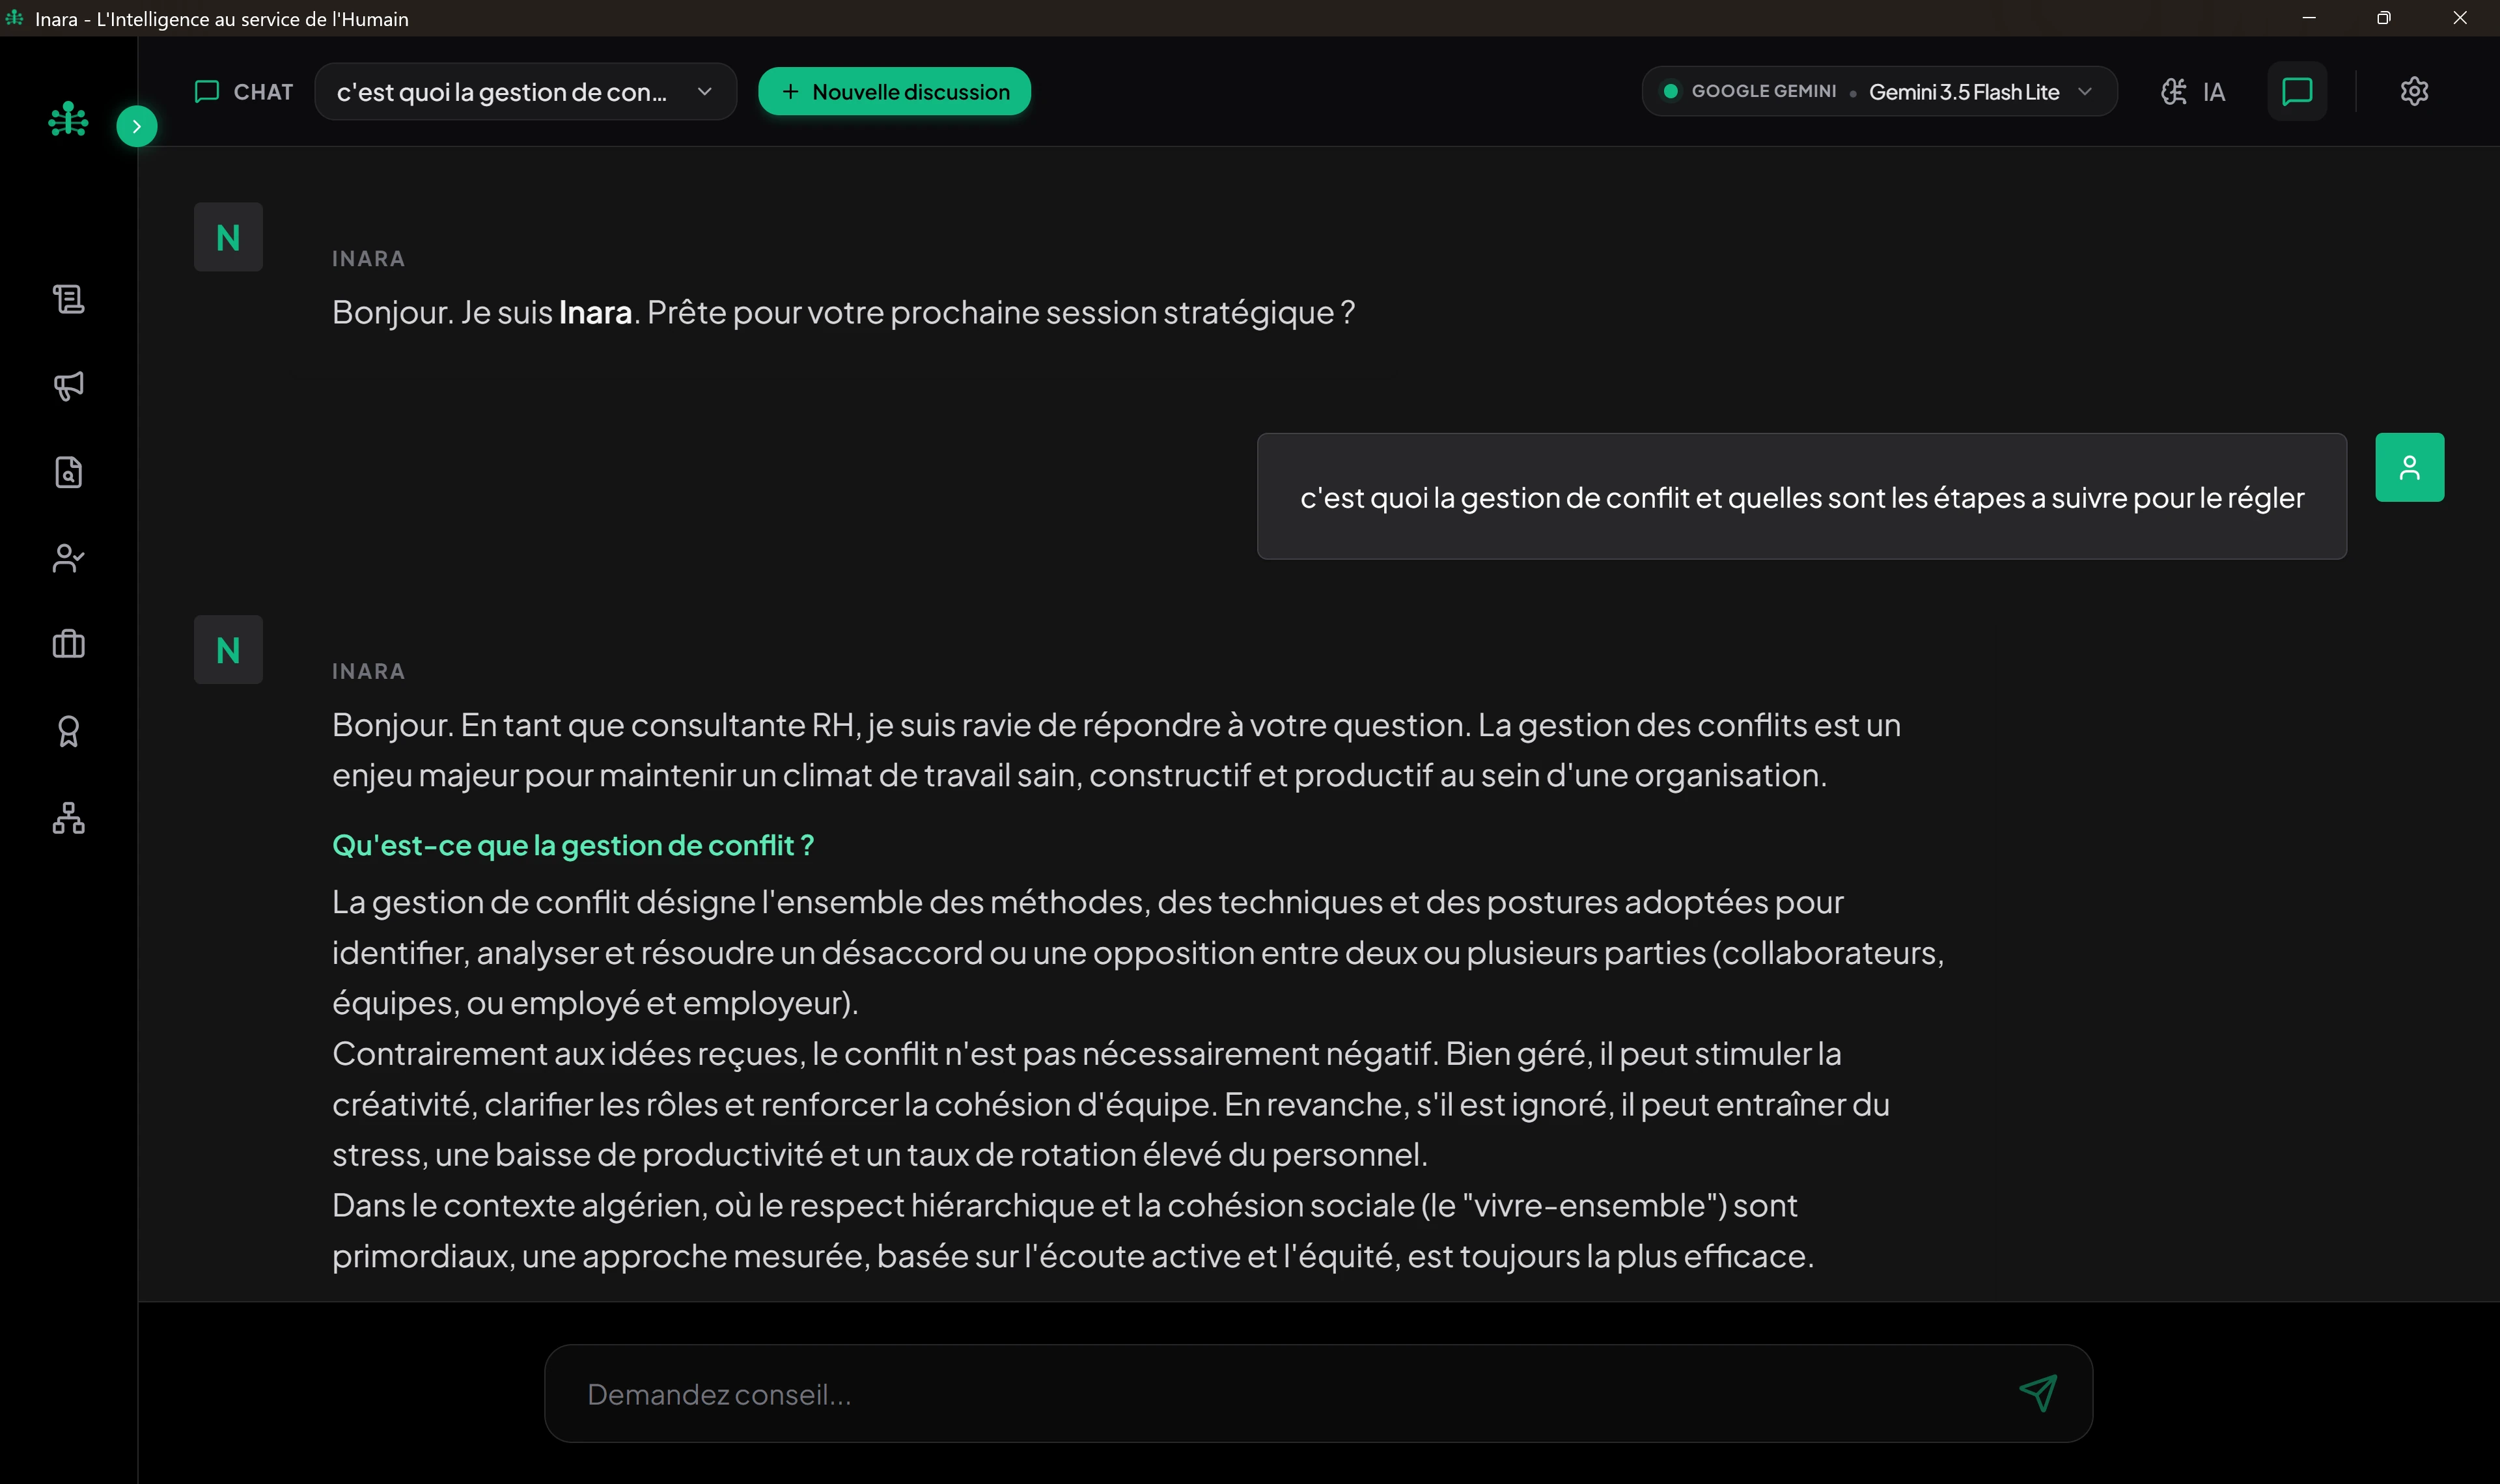
Assistant Inara
Conversational HR advisory copilot executing on your local model
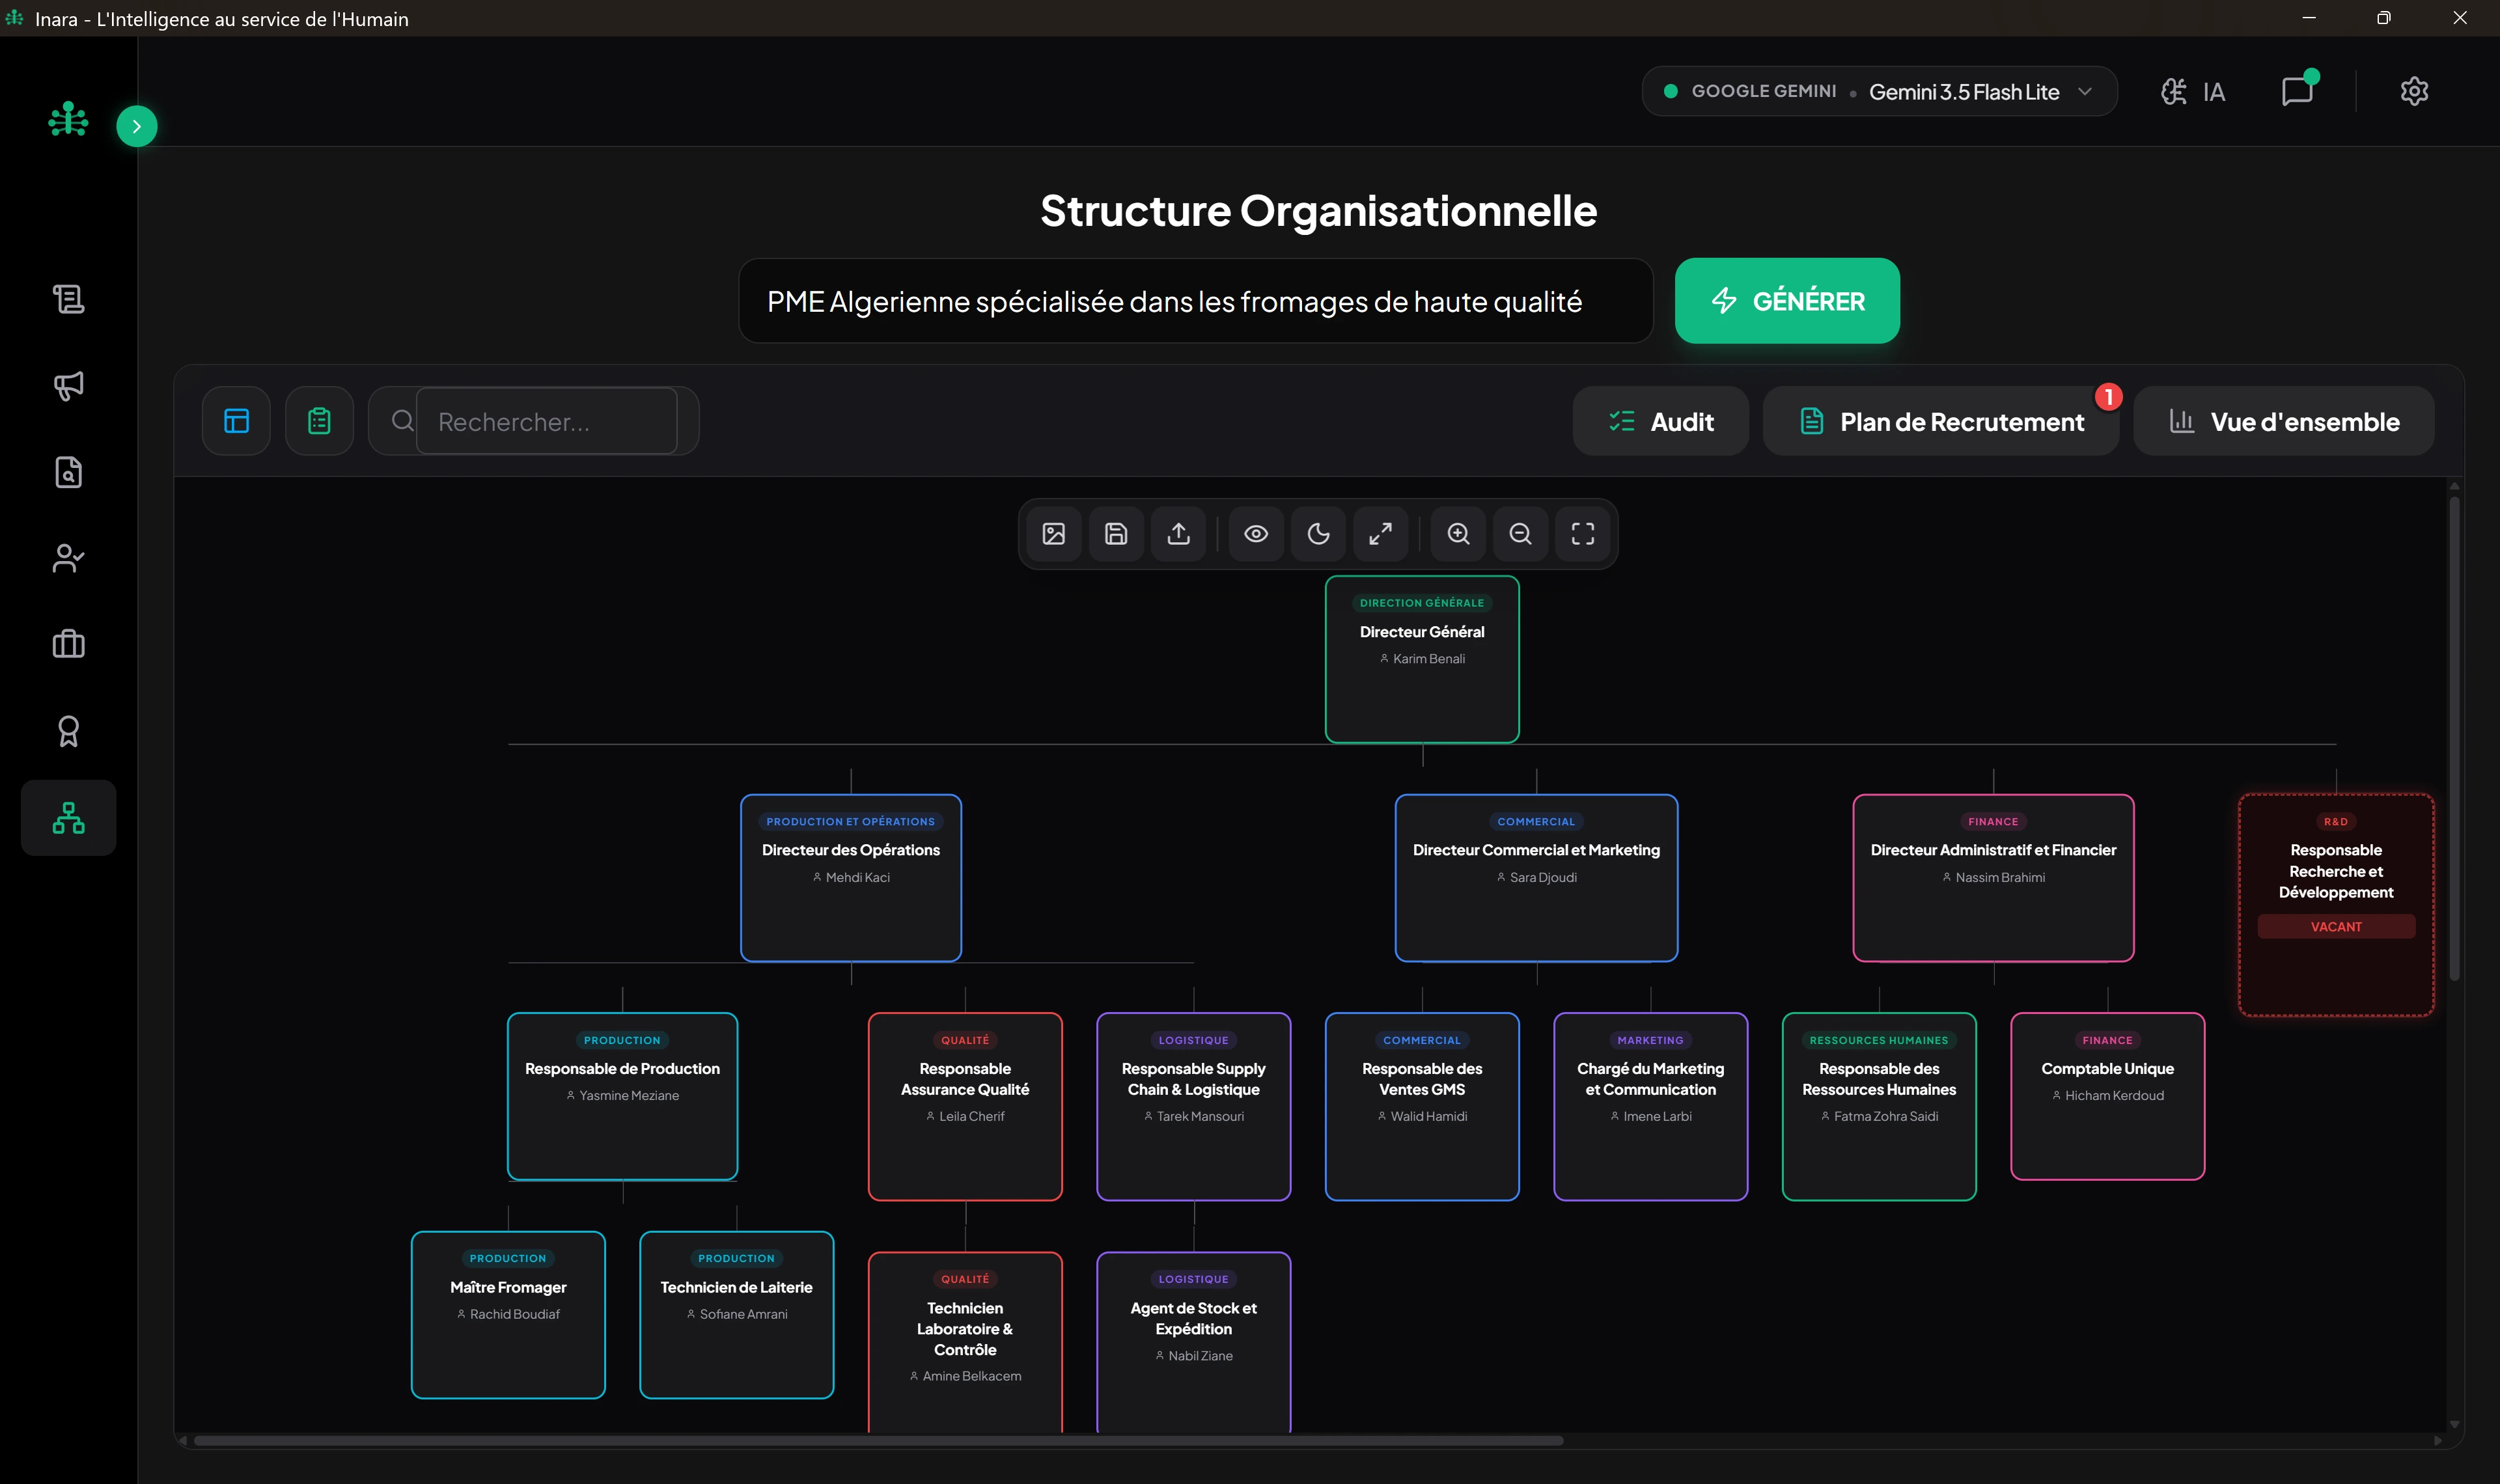
Organizational Structure
Org chart modeling and HR organizational health audit running locally